Agent Efficiency: Agile Metrics for the AI Coding Era
Key Takeaways
- Velocity is officially broken as a primary forecasting metric; AI inflates story points without increasing true delivered value.
- The bottleneck in agile delivery has shifted permanently from code generation to human verification and review.
- Agent Efficiency measures the friction between AI drafting speed and human review effort, replacing legacy throughput.
- Metrics like code churn and escaped-defect rates serve as mandatory guardrails against unseen "velocity inflation."
- Product leadership must pivot focus from output metrics to the DX Core 4 and EBM Key Value Areas to determine real ROI.
For fifteen years, velocity was the number every PMO trusted to forecast delivery.
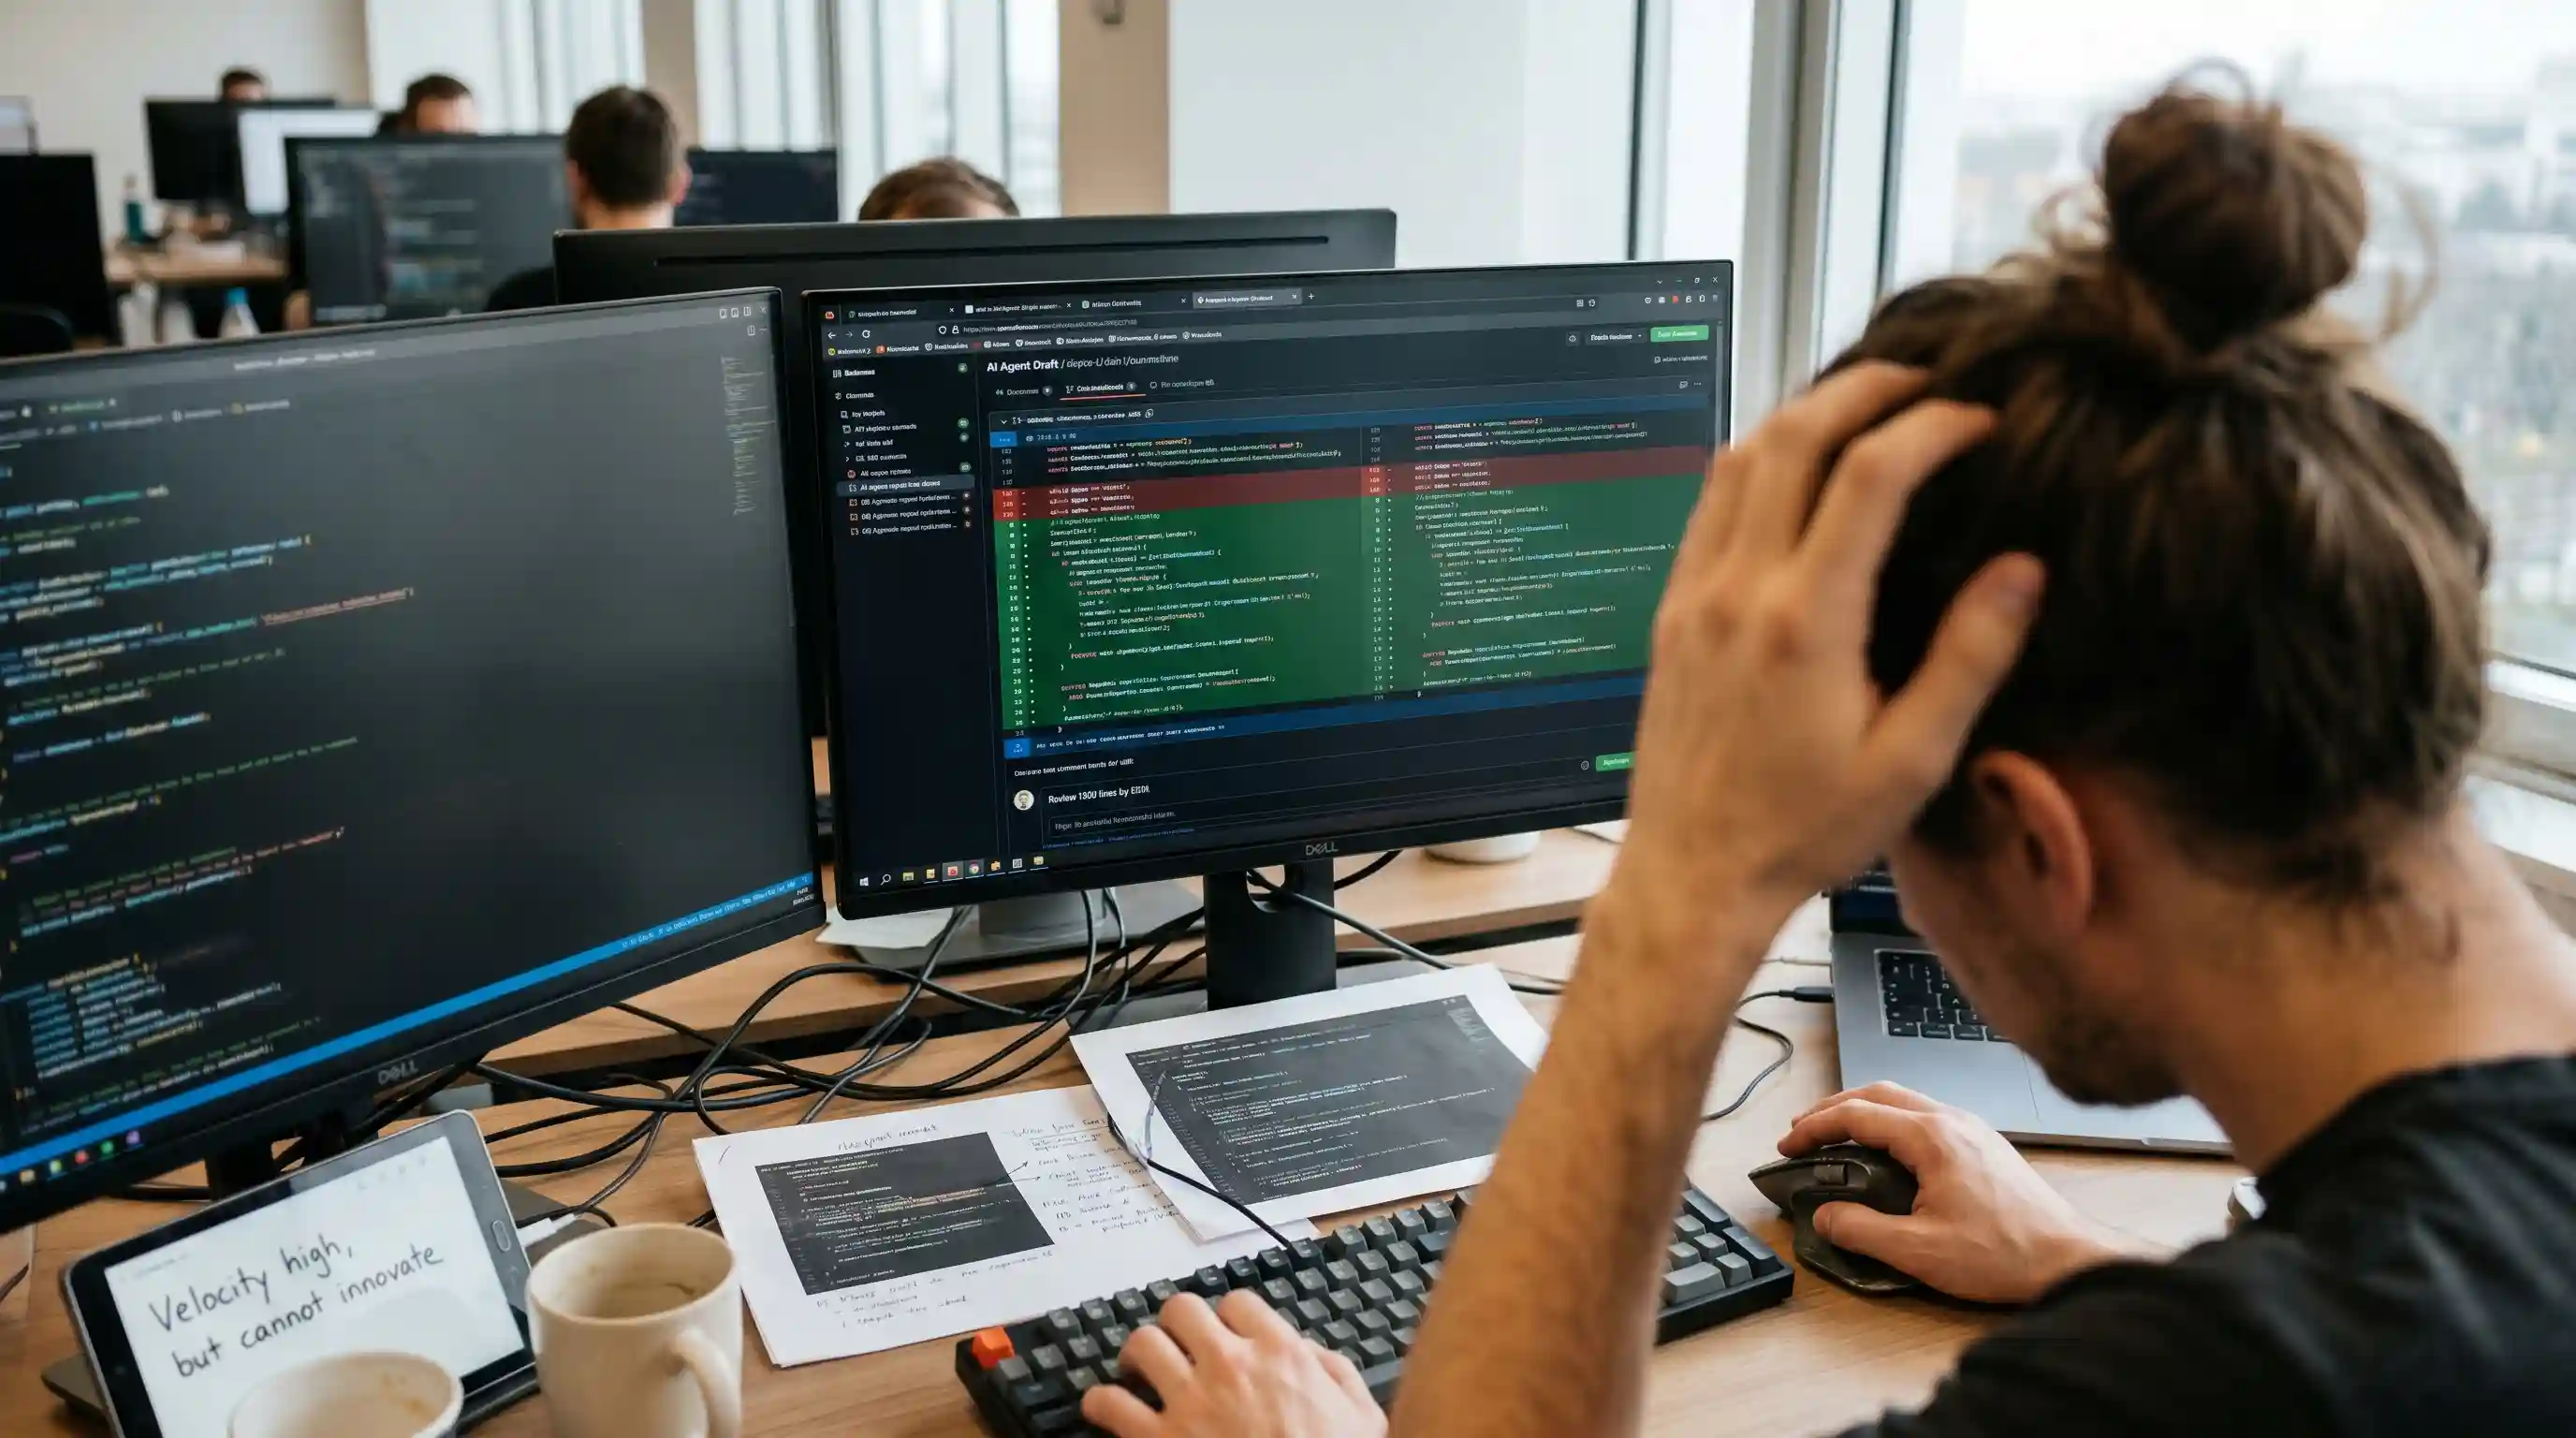
Then coding agents arrived, story-point throughput spiked 5x in a single sprint, and the business shipped no more value than the quarter before.
The metric you steer the portfolio with is now actively lying to you.
This agentic era agile metrics guide gives you the replacement measurement stack before your next QBR exposes the gap.
Executive Summary: The Old Metric Stack vs. the Agentic-Era Stack
In 2026, AI agents do the drafting while humans do the verifying.
That single shift breaks effort-based metrics and forces a new measurement model. Here is the at-a-glance translation:
| Classic Metric (pre-AI) | Why It Breaks With Agents | Agentic-Era Replacement |
|---|---|---|
| Velocity (story points / sprint) | AI collapses drafting effort to near-zero, inflating points without value | Agent Efficiency (human–AI friction score) |
| Lines of code / commits | Hides rework; AI raises churn and reverts | Code churn & rework rate |
| Individual throughput | Ignores the bottleneck shifting to human review | Blended human + AI throughput |
| Story points (as effort) | Effort is no longer the constraint; complexity is | Recalibrated complexity + Monte Carlo |
| DORA alone | Measures delivery speed, not AI's hidden quality cost | EBM Key Value Areas + DX Core 4 |
The one-line takeaway: stop measuring how fast work is produced and start measuring the friction between your silicon workforce (agents) and your carbon workforce (humans).
That friction is exactly where value is now won or lost.
Why Agile Metrics Broke the Moment AI Joined the Team
Every traditional agile metric shares one buried assumption: that effort and output are roughly proportional.
A 5-point story took more human hours than a 2-point story, making points a reasonable proxy for progress and capacity.
Coding agents severed that link. When an agent generates a feature scaffold in seconds, the "effort" the points were measuring evaporates.
Your throughput chart now measures the machine's speed, not your team's actual delivered value.
The velocity inflation trap
The first symptom most PMOs see is a velocity spike that no one can explain to the board.
A team running Copilot or Cursor posts 60 points where it used to post 30, tricking leadership into budgeting quarters against numbers that will not hold.
The inflation is real but the capacity is not, because verification—reviewing, testing, securing, and integrating—did not get faster.
We unpack the full diagnostic pattern in our deep-dive on velocity inflation.
PMO Warning
If you re-baseline velocity upward after an AI rollout and lock roadmap commitments to it, you are forecasting on a number engineered to be gamed.
Treat any post-AI velocity jump as unverified capacity until lead time and escaped-defect rate confirm it.
The Misconception Costing PMOs Millions: "Faster Coding = Faster Delivery"
Here is the counter-intuitive insight most AI-productivity vendors will not lead with.
Accelerating code generation almost never accelerates end-to-end delivery; it usually does the opposite at the system level.
The reason is queueing theory. When you speed up one station on an assembly line without expanding the next, you just build a larger pile of work-in-progress.
AI made the coding station hyper-fast, but the human review and release stations did not change.
Pull requests arrive faster than reviewers can absorb them. Batch sizes grow, and lead time worsens even as "coding speed" charts soar.
Pro Tip
Run a one-sprint experiment: hold AI tooling constant, cap PR size, and add a second reviewer.
If lead time drops, you have proven the constraint is human review, not coding—and you can stop over-investing in raw generation speed.
What "Agent Efficiency" Actually Measures
Agent Efficiency is an emerging measurement lens that reframes the team as two collaborating workforces.
You now operate a silicon workforce of agents alongside a carbon workforce of humans.
The metric tracks the friction between them rather than the raw output. High agent output with high friction is not productivity—it is motion.
Roughly, it measures value-delivering output accepted into production relative to the human effort spent supervising and correcting agent work.
We walk through the exact calculation in the dedicated spoke on the agent efficiency score.
The New Core Metrics: Churn, Throughput, and EBM
1. Code Churn and Rework Rate
AI models write code rapidly, but they frequently require massive rewrites or rollbacks.
Tracking code churn isolates the reality of how often AI-generated code survives human review or production testing.
Pair churn with escaped-defect rate, and you establish a quality floor that makes inflated velocity impossible to fake.
The full method lives in our churn deep-dive and escaped-defect rate guide.
2. Evidence-Based Management (EBM) in the AI Era
The Evidence-Based Management framework focuses heavily on Unrealized Value and Time-to-Market.
With AI handling rote generation, your teams have more bandwidth to innovate and capture that Unrealized Value.
Our complete KVA-to-agent mapping, with the leading indicators for each, is in our EBM AI-era KPIs spoke.
Boardroom Note
When you brief executives, lead with Unrealized Value and Ability-to-Innovate, not delivery speed.
Speed is the metric AI flatters; innovation capacity is the metric AI silently mortgages to achieve that speed.
DX Core 4 vs. DORA: AI Measurement Frameworks
While DORA metrics transformed the DevOps era, the DevEx (DX) Core 4 is rapidly emerging as the superior framework.
DORA alone measures delivery speed, failing to expose AI's hidden quality or systemic pipeline costs.
The head-to-head analysis, including which exposes AI's hidden costs, is in our DX Core 4 framework spoke.
For classical definitions of cycle time and throughput, our legacy Agile Metrics & Forecasting Guide remains the canonical reference.
Frequently Asked Questions (FAQ)
What is the new agile metrics stack for the AI era?
The new stack shifts focus from effort-based tracking to outcome and flow. Key metrics include Agent Efficiency, code churn and rework rate, blended throughput (human + AI), and EBM Key Value Areas.
Why is velocity broken when teams use AI coding agents?
Velocity assumes points reflect effort. Agents collapse drafting effort to near-zero, so points spike while verification, review, and integration effort stay high. The result is inflated capacity that does not translate into delivered value, making roadmap forecasts unreliable.
What is the Agent Efficiency metric?
Agent Efficiency measures the friction between your "silicon" workforce (agents) and "carbon" workforce (humans). It measures value-delivering output accepted into production relative to human effort spent supervising, correcting, and integrating agent work. Higher means the two workforces genuinely compound.
How do you prove AI ROI to leadership without using velocity?
Tie AI to outcomes, not output. Show lead-time and change-failure improvements, stable or falling churn, and movement in EBM's Unrealized Value and Time-to-Market. Pair delivery evidence with the value-realization and FinOps views to give leadership a complete, defensible ROI picture.
Which agile metrics still work in the AI agent era?
Outcome and flow metrics survive: lead time, cycle time, change-failure rate, escaped-defect rate, and the EBM Key Value Areas. Effort and volume metrics — velocity, lines of code, commits — do not, because AI distorts the relationship between effort and result.
How do you stop AI from gaming your delivery dashboard?
Use a balanced metric set instead of one headline number, keep every metric team-level rather than individual, and apply Goodhart's Law deliberately: design the set so improving one figure dishonestly visibly worsens another, making gaming self-defeating and easy to spot.