Silicon vs Carbon: The Agent Efficiency Metric Explained
Key Takeaways
- Effort is obsolete: AI coding agents reduce drafting effort to near-zero, making traditional velocity a highly inflated vanity metric.
- The new paradigm: Teams must be viewed as two distinct workforces: a silicon workforce (agents) and a carbon workforce (humans).
- Measure friction, not output: Agent efficiency tracks the friction between an AI generating code and a human reviewing it.
- Quality over volume: High AI output with high human verification effort is not productivity; it is an unmanaged bottleneck.
- EBM alignment: Agent efficiency pairs perfectly with Evidence-Based Management to ensure your team is protecting its Ability to Innovate.
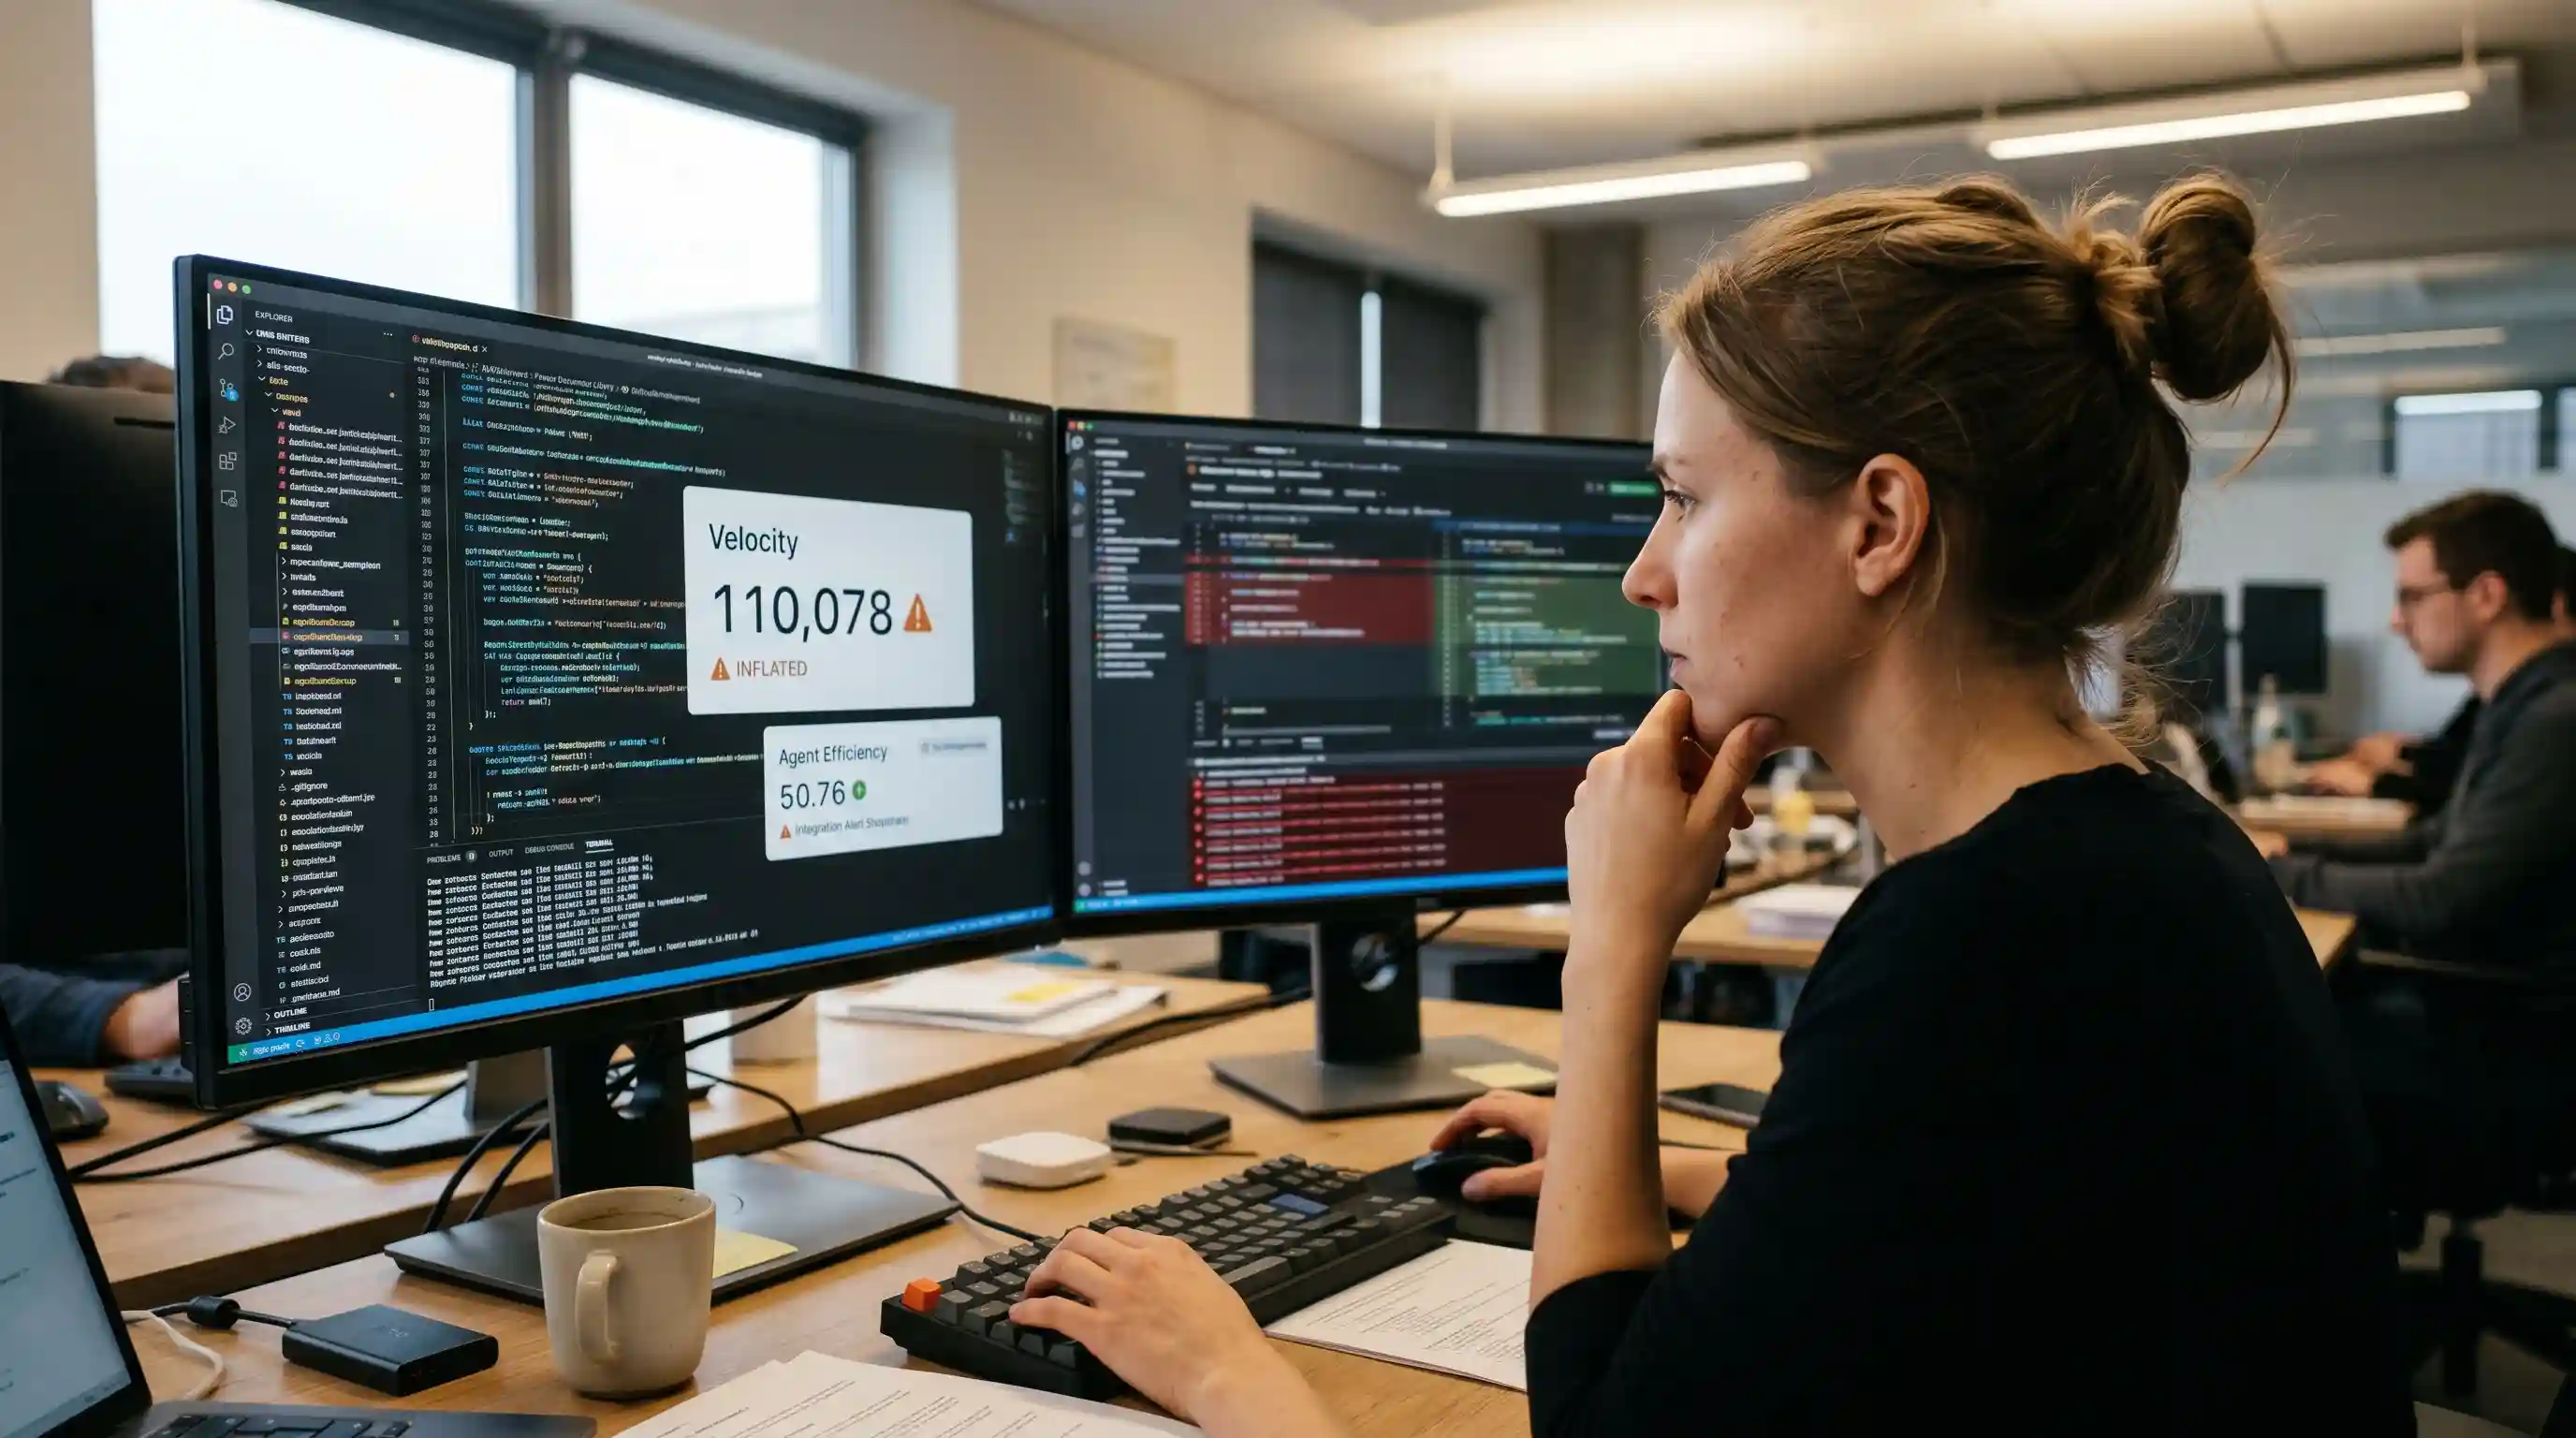
Velocity counts effort that AI just made near-zero. If you rely on traditional story points to measure a team equipped with coding agents, your dashboard is actively lying to you.
When your team fakes 100x output without moving the needle on actual delivery, you are experiencing the primary failure mode of the AI era. If you’ve read our complete guide on agentic-era agile metrics, you already know the baseline rule: effort-based throughput is dead.
To survive a modern QBR audit, leaders must stop measuring raw coding speed and start measuring the friction between their human and AI workforce.
The Silicon vs. Carbon Workforce Explained
The fundamental shift in agentic-era delivery is workforce composition. You no longer manage a single team of human developers. You manage a blended environment.
The silicon workforce consists of your AI coding agents, Copilots, and automated tools. Their primary function is rapid drafting, scaffolding, and boilerplate generation. They operate at unimaginable speeds but lack business context and deep architectural foresight.
The carbon workforce is your human engineering team. Their role has fundamentally shifted from raw code creation to complex verification, security auditing, and architectural alignment.
The framing of "silicon vs carbon workforce" emerged rapidly from the Scrum.org community in early 2026. It forces PMOs to realize that accelerating the silicon side does not magically accelerate the carbon side.
Why Velocity Becomes a Vanity Metric with AI
Traditional velocity assumes that story points reflect human effort. A 5-point story required more typing, thinking, and testing than a 2-point story.
AI coding agents sever this correlation completely. An agent can draft a 5-point feature in thirty seconds. The drafting effort collapses, but the points remain on the board.
Because verification complexity stays high while drafting effort drops to near-zero, velocity spikes artificially. Your charts will show massive productivity gains, but your actual release cadence will remain flat.
As we have covered extensively on our legacy hub, tracking performance purely through output volume turns velocity into a vanity metric. It becomes a textbook example of Goodhart’s Law.
How to Calculate the Agent Efficiency Metric
Agent efficiency is the antidote to this velocity inflation. It is a delivery-mechanics metric designed to track how cleanly humans and agents produce shippable work together.
Instead of asking "How much did we build?", Agent Efficiency asks "How much human effort was required to make the machine's output usable?"
Measuring the Friction Score
The friction score is the core of agent efficiency. It is calculated as the ratio of value-delivering output accepted into production versus the total human effort spent supervising, correcting, and integrating that AI-generated work.
If your silicon workforce generates 10,000 lines of code, but your carbon workforce spends three days rewriting, reviewing, and reverting it, your friction score is abysmal.
A high agent efficiency score means the AI output is highly accurate, requiring minimal human intervention to reach the "Done" state. This proves your two workforces are genuinely compounding their efforts.
Is Agent Efficiency an Evidence-Based Management Metric?
Agent efficiency is a crucial enabler of empiricism in Scrum, but it is a delivery metric, not an ultimate value metric.
However, it directly supports the Evidence-Based Management (EBM) framework. When agent efficiency drops—meaning human reviewers are overwhelmed by low-quality AI code—it directly threatens your team's Ability-to-Innovate.
Human engineers bogged down in AI rework cannot focus on new customer value. To get the full boardroom picture, you must map your agent efficiency data directly against your EBM AI-era KPIs.
Can the Agent Efficiency Score Be Gamed?
Any metric can be gamed if used as a performance target rather than a learning tool.
If you tie bonuses to agent efficiency, developers might start rubber-stamping AI pull requests without proper review. To prevent gaming, Agent Efficiency must never sit on a dashboard alone. It must be paired with counter-metrics.
If a team artificially inflates their agent efficiency by skipping code reviews, their code churn and rework rate will immediately spike as bugs escape into production. Balancing efficiency metrics against quality metrics ensures the silicon and carbon workforces remain in honest alignment.
Frequently Asked Questions (FAQ)
What is agent efficiency in agile?
Agent efficiency measures the operational friction between AI agents generating work and human developers verifying it. It tracks how smoothly machine output is converted into releasable value, acting as a reality check against inflated output metrics in the agentic era.
How is agent efficiency different from velocity?
Velocity tracks the raw volume of effort or complexity completed in a sprint. Agent efficiency tracks the ratio of usable value created versus the human supervision required. Velocity inflates when AI writes code; agent efficiency reveals the true integration cost.
What does silicon vs carbon workforce mean?
This is a 2026 framing model. The "silicon workforce" refers to AI coding agents responsible for high-speed drafting. The "carbon workforce" refers to human engineers responsible for architectural judgment, security, and complex verification.
How do you calculate agent efficiency?
It is calculated by comparing the volume of AI-generated work successfully deployed to production against the human hours spent reviewing, reverting, and correcting that specific code. A higher ratio indicates low friction and healthy human-AI collaboration.
Why does velocity become a vanity metric with AI?
AI collapses the effort required to draft code to near-zero, but the verification effort remains high. Velocity spikes because points are completed quickly, but actual value delivery stalls at the human review bottleneck, creating an illusion of massive speed.
Is agent efficiency an Evidence-Based Management metric?
It is not one of the four core EBM Key Value Areas, but it is a vital leading indicator for them. Poor agent efficiency directly degrades a team's Ability-to-Innovate because humans spend all their capacity cleaning up after AI agents.
What is the friction between human and AI work?
Friction encompasses all the non-value-adding activities required to merge AI work. This includes time spent reading dense AI pull requests, rewriting hallucinated functions, fixing security vulnerabilities introduced by agents, and managing code reverts.
Can agent efficiency be gamed?
Yes, developers could artificially improve the score by blindly approving AI-generated code without review. To prevent this, PMOs must always pair agent efficiency with quality counter-metrics like code churn, revert rates, and escaped-defect rates.
Does agent efficiency replace story points?
It replaces story points as a measure of effort and productivity. However, story points can still be retained specifically to measure the complexity and uncertainty of a problem, which AI has not inherently solved.
How do you report agent efficiency to stakeholders?
Report it alongside lead time and code quality. Frame it to leadership not as "how fast are we coding," but as "how effectively is our human talent leveraging our AI investment without degrading system stability or innovation capacity."